 AI Tools Review Editorial Team
Software engineering is evolving from manual coding to the orchestration of AI fleets. With the release of Claude Code 2.1 in early 2026, Anthropic has solidified its CLI-first approach as the gold standard for agentic development.
Rather than acting as a simple "copilot," Claude Code now functions as a full-fledged Junior Developer, capable of running tests, debugging multi-file regressions, and managing complex Git state autonomously.
Parallel Agent Teams
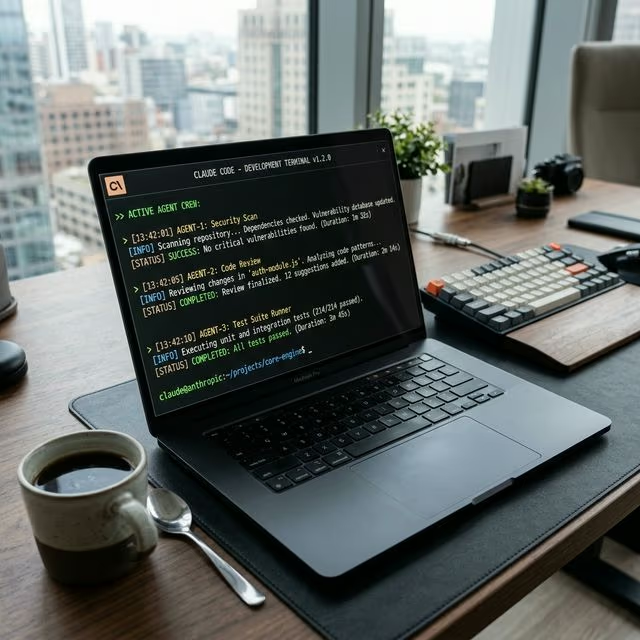
A breakthrough feature in the 2.1 update is "Agent Teams." Developers can now spawn multiple sub-agents to handle parallel investigations.
Mechanically, a subagent is a Markdown file with YAML frontmatter. Drop it in .claude/agents/ to share it with the team through version control, or in ~/.claude/agents/ to keep it personal across every project. The frontmatter declares a name, a description telling Claude when to delegate to it, an optional tool allowlist, a model, and a permission mode.
A minimal subagent definition:
---
name: code-reviewer
description: Reviews changed code for quality and security issues
tools: Read, Glob, Grep
model: sonnet
---

You are a senior code reviewer. Analyse the diff and give
specific, actionable feedback on quality and security.
The point of the isolation is context hygiene rather than raw speed. Each subagent starts with a fresh window containing its own system prompt and the delegation message, but none of your conversation history, and it returns a summary rather than the full transcript of everything it read. A reviewer does not need the exploratory reasoning that produced the implementation, and keeping that noise out of the main session is what allows a long task to stay coherent.
The permission model is the underrated half. Because tools are declared per agent, a documentation agent can be given read access and nothing else, while a deployment agent gets shell access but no path to your secrets. You can allowlist with tools, denylist with disallowedTools, and strip MCP access wholesale with a pattern such as mcp__*. That is a materially stronger guarantee than instructing a single agent to behave itself.
There are hard ceilings worth knowing before you design around this. By default Claude Code runs a maximum of 20 subagents concurrently, and subagents may spawn their own subagents up to three layers deep. Both are configurable through environment variables, but the defaults are sensible: beyond roughly that width, coordination overhead and merge conflicts tend to cost more than the parallelism gains. Three built-in agents ship out of the box, Explore for fast read-only codebase reconnaissance, Plan for research during plan mode, and a general-purpose agent for multi-step work.
The primary Claude instance acts as a project manager, coordinating these sub-agents and deciding what work each one receives. It is worth being clear-eyed that this is orchestration rather than magic: agents working on genuinely overlapping files will still conflict, and the reliable pattern is to split work by directory or concern so that each agent owns its own surface.
Agent Skills Marketplace
Perhaps the most significant business move is the launch of the Agent Skills Marketplace. These are reusable "skill-sets" (formatted in Markdown) that define tribal knowledge and specific workflow procedures.
- Standardized SOPs: Ensure every agent follows your company's specific security and style guidelines.
- Rapid Onboarding: New team members can instantly share their custom agents with the global marketplace.
A skill is deliberately unglamorous: a Markdown file in a named folder under .claude/skills/ or ~/.claude/skills/, describing a procedure in plain prose. Claude loads it when the task matches. There is no DSL to learn and no runtime to install, which is exactly why the format has spread: the best prompt anyone on your team has written can become a reusable capability in about a minute, and it lives in your repository where it can be reviewed like any other file.
Skills also compose with subagents. A subagent definition can preload specific skills into its context, so a release agent can start every run already knowing your versioning conventions, changelog format and deployment checklist without anyone pasting them in. Packaged together with agents, hooks and MCP server definitions, a set of skills becomes a plugin, and plugins are what the marketplace actually distributes.
The quality problem that follows is real and Anthropic has started addressing it with tooling rather than curation alone. Claude Code now ships a claude plugin eval command that runs a plugin's evaluation suite against Claude Code and produces scored, reproducible results as JSON and an HTML report. If you are publishing skills internally, that is the mechanism that turns "this prompt worked for me" into something a platform team can sign off. It is also the first honest answer to an obvious objection: a marketplace of untested Markdown instructions is a supply chain, and supply chains need tests.
MCP: Connecting Claude to Your Stack
Agent teams are only as useful as the information they can reach, which is where the Model Context Protocol comes in. MCP is an open standard for exposing external systems to a model as tools, and Claude Code speaks it natively. In practice that means agents can query an issue tracker, read from a database, pull error traces from monitoring, drive a browser, or hit an internal API, without anyone writing bespoke glue for each one.
The typical 2026 setup connects a handful of servers: Jira or Linear for tickets, Postgres for schema and data questions, Sentry for production errors, Figma for design references, and an internal documentation source. A debugging session then looks less like pasting stack traces into a terminal and more like asking Claude to correlate a Sentry issue with the commit that introduced it and the ticket that requested it.
Restraint matters more than coverage here. MCP servers can be scoped to individual subagents rather than mounted globally, and they should be: the more tools presented in a single call, the more likely the model is to route poorly. Give each agent the two or three servers its job requires and nothing more. The same logic that makes narrow tool allowlists a security win makes them an accuracy win.
Enterprise Guardrails
Autonomy is only acceptable if the blast radius is bounded, a lesson the industry keeps relearning (see our write-up of the Claude Mythos sandbox escape). Claude Code's answer is operating-system-level isolation for the Bash tool, configured through the /sandbox command. Rather than approving every command individually, you declare which files and which network domains commands may touch, and the OS enforces that boundary for the command and all of its child processes.
The implementation differs by platform. On macOS it uses Apple's built-in Seatbelt framework, so there is nothing to install. On Linux and WSL2 it relies on bubblewrap for unprivileged filesystem isolation, with network traffic relayed through a local proxy that checks an allowlist and returns a 403 for anything denied. Native Windows is not supported; Windows users run Claude Code inside a WSL2 distribution. By default, write access is limited to the working directory and its subdirectories while read access covers the system except explicitly denied paths.
The limitation is important and frequently misunderstood: the sandbox wraps Bash only. Read, Edit, MCP servers and hooks still run on the host unless you escalate to a stronger isolation layer such as a dev container or a virtual machine. If your threat model includes a prompt-injected agent writing to a file it should not, sandboxed Bash alone will not save you, and the right answer is a container or VM around the whole session.
Native integration with the Model Context Protocol (MCP) enables your agents to pull data from Slack, Jira, and Google Docs securely, with fine-grained per-task permission prompts. Combined with per-agent tool allowlists and managed settings that let an organisation define agents centrally and override anything a developer configures locally, this is the first version of Claude Code that a security team can realistically sign off for regulated work.
Automating Complex Workflows
Claude Code 2.1 excels at long-sustained tasks. Whether it is a whole-repo refactor or an automated dependency update crossing 100+ files, the system maintains context and "checks-in" with the user only when critical decisions are needed.
Several 2.1 additions are aimed squarely at that kind of work rather than at interactive chat. The claude ultrareview subcommand runs non-interactively, which makes it usable from CI or a shell script rather than only from a terminal session. Settings such as bashOutputMaxChars and taskOutputMaxChars raise how much command and background-task output reaches the model inline before it is spilled to a file, which matters when a test run produces thousands of lines and the useful signal is at the end. A maxEffortLevel setting caps reasoning effort globally or per model, including on Bedrock, Vertex and Foundry deployments, which is how platform teams keep an enthusiastic agent from spending an afternoon's budget on a linting fix.
The practical pattern that has emerged for large migrations is three-phase. First, an Explore pass with read-only agents to map the surface and produce a written plan. Second, a fan-out where each agent owns a directory or module and works inside its own context. Third, a consolidation pass run by the primary session that reconciles the results, resolves conflicts and runs the full test suite once. Skipping the first phase is the single most common cause of expensive failure: agents that start editing before the plan exists generate work that later agents have to undo.
A useful discipline throughout is to make the agent's reasoning reviewable. Have agents write their plan to a file before executing it, keep commits small and scoped, and treat the diff rather than the conversation as the artefact you review. Our guide to mastering Claude Code workflows goes into the day-to-day habits in more detail.
Pricing & Availability
Claude Code remains free to download and use for all Claude Pro ($20/month, approx £16) and Enterprise subscribers. Users pay only for the tokens consumed during task execution.
The tiers above Pro exist because agent teams are expensive by construction: running five subagents in parallel consumes roughly five times the tokens of running one. Max 5x at $100/month (approximately £80) and Max 20x at $200/month (approximately £160) buy proportionally more capacity per session, and for teams the Premium seat is the tier that includes Claude Code rather than the standard one. Usage is metered two ways on every paid plan: a session limit that resets on a five-hour cycle, and a weekly limit across all models. Anyone planning to run parallel agents routinely should assume the weekly cap, not the session cap, is the one they will meet first.
Model choice is the other cost lever, and it is per agent. A subagent's frontmatter can pin it to a cheaper model, so an Explore agent reading files can run on Haiku while the agent writing the actual patch runs on Opus. An environment variable can force every subagent onto a single model organisation-wide, which is a blunt but effective way to stop a fan-out from quietly becoming the largest line on the bill. We break the numbers down further in our Claude Code pricing guide.
Where It Still Falls Short
Three honest caveats, because the marketing around agentic development has run some distance ahead of the experience.
Parallelism has a ceiling that is lower than the configuration allows. The default of 20 concurrent subagents is a technical limit, not a recommendation. Past a handful of agents, the coordination cost of reconciling their output usually exceeds the time saved, particularly on codebases where modules are tightly coupled. Splitting work by directory helps; splitting a single tangled module across three agents does not.
The sandbox is narrower than most people assume. It covers Bash. Everything else runs on the host. Teams that read "sandboxed" and grant broad autonomy on that basis are exposed to exactly the class of failure the feature appears to prevent.
Review is still the bottleneck, and it has moved. Generating a 100-file change is now easy; understanding whether it is correct is not, and no amount of agent orchestration removes the need for a human to own the result. The teams getting real value from agent teams in 2026 are the ones that invested in tests, small reviewable commits and clear module boundaries first. The ones that did not have simply automated the production of work they cannot verify.