 AI Tools Review Editorial Team
Quick Answer:
Meta released Muse Wonder and Muse Wonder Full on 12/10/2026, calling them its first frontier models. Muse Wonder costs $4 / $20 per million input / output tokens (roughly £3 / £15), the same list price as Claude Opus 5.5, with a 1M-token context window. In Meta’s own benchmark table Wonder Full leads six rows, but Opus 5.5 also leads six, and the independent Artificial Analysis index puts Opus 5.5 (58) ahead of Wonder Full (56) and Muse Wonder (52). Every Meta-chart number here is self-reported.
Meta has spent over a year rebuilding its AI effort, and Muse Wonder is the first release it is willing to compare directly with the best from Anthropic and OpenAI. Two of our tracked creators, Matthew Berman and WorldofAI, covered it within hours of launch, one impressed and one openly sceptical that it is “Opus 5.5 level”.
This guide pulls together what Meta says, what independent trackers say, and where the two disagree. We separate verified facts (names, access, pricing) from vendor claims (benchmarks, safety), and we point out which comparisons we would not trust yet.
Matthew Berman reacts to Meta\u2019s Muse Wonder launch on 13/10/2026.
WorldofAI runs its own WoAI Bench tests to check Meta\u2019s claim of Opus 5.5-level performance.
Executive Summary
- What launched: Muse Wonder and Muse Wonder Full, announced by Meta on 12/10/2026 as its “most capable models to date”, built on Muse Spark.
- Access: Muse Wonder through the Meta Model API and Muse Code; Wonder Full for Muse Code subscribers only; the Muse app follows, subscribers first.
- Price: $4 input and $20 output per million tokens for Muse Wonder, matching Claude Opus 5.5 at list price, with a 1M-token context window and text output only.
- Benchmarks: mixed. Meta’s own chart shows wins on agentic, memory and long-coding rows and losses on ProgramBench, OSWorld, Terminal-Bench and HealthBench.
- Independent view: the Artificial Analysis Intelligence Index quoted by Fello AI ranks Opus 5.5 first at 58, with Wonder Full on 56 and Muse Wonder on 52.
- Safety: Meta says it cannot rule out Wonder Full reaching its high-risk threshold for chemical and biological misuse without mitigations. A full safety report is promised “soon”.
- Weights: closed. No open-weight release is mentioned.
Our view: a credible entry that makes Meta a real fourth option for agent builders, especially where memory and long-running tasks matter. It is not yet a proven Opus 5.5 replacement, and the evidence that it is will have to come from outside Meta. For the previous step on this ladder, see our Muse Spark 1.3 review.
What Meta Actually Launched
According to Meta’s announcement, Muse Wonder and Muse Wonder Full are the latest step on what the company calls its scaling ladder, and the company says they deliver state-of-the-art performance on personal and professional agentic tasks. TechCrunch reports they are Meta’s first attempt at a frontier model, larger and more capable than the lightweight, low-latency Muse Spark, and the first such release since Alexandr Wang restructured Meta’s AI efforts in August 2025. Meta says the models were trained at its Prometheus data centre in central Ohio, which came online earlier in 2026, and Quartz reports an internal codename of “Watermelon”.
The split between the two models matters for buyers. Muse Wonder is the one you can call through the API. Muse Wonder Full is restricted to Muse Code subscribers, and Fello AI notes that it is not on the public API and that Muse Code plans cost $50 and $200 a month. CNBC reports that the Muse personal agent app has paid tiers at $20 or $100 a month. Meta says Wonder will soon power experiences in the Muse app, rolling out first to subscribers, and consumer availability is described inconsistently, with no date for free users.
If you have followed Meta’s run of Muse releases, from Spark to the agent and the small open-weight model, the positioning is clear. Spark was cheap and fast. Wonder is aimed at the expensive end of the market, where Meta has so far been absent. For the agent product these models will sit inside, see Meta’s Muse agent and its secure VM and our look at Muse for small business.
Active Memory and Active Focus
Meta’s two named features are Active Memory and Active Focus. Active Memory carries what matters across conversations and brings back relevant details. Active Focus is Meta’s term for persistence: the model keeps working towards a goal when a task gets hard, tries other approaches, recovers from errors, asks for clarification when needed and checks in before important actions.
TechCrunch quotes a Meta research scientist, Kavya Kopparapu, saying the team worked hard so that the model can remember what matters to users over days, weeks and months. That is a product bet rather than a benchmark: a personal agent that remembers is only useful if it remembers correctly, which is hard to measure from the outside. Meta’s own MemoryBench row, where Muse Wonder scores 85.6 against 81.5 for Opus 5.5, is an internal test, so treat it as direction rather than proof.
For a wider look at why memory and agency are becoming the battleground, see our piece on the human skills AI makes more valuable, which discusses personal agents, and our coverage of OpenMuse, the open-source personal agent.
Benchmarks: Meta’s Table, Honestly Read
The figures below come from Fello AI’s transcription of Meta’s chart. Meta ran its models at maximum reasoning effort unless noted. We have not been able to open Meta’s model card ourselves, so check the numbers against it before quoting them elsewhere.
| Benchmark (Meta’s chart) | Wonder Full | Muse Wonder | Fable 5.1 | GPT-6 Astra | Opus 5.5 |
|---|---|---|---|---|---|
| Personal Superintelligence Index (internal) | 59.1 | 54.3 | 49.9 | 54.5 | 55.2 |
| Harvey LAB-AA (legal agents) | 13.1 | 10.0 | 6.4 | 8.6 | 4.2 |
| Vals Finance Agent V2 | 59.1 | 56.6 | 58.9 | 53.5 | 58.6 |
| HealthBench Pro | 62.3 | 60.5 | 62.1 | 65.3 | 65.6 |
| AutomationBench-AA (business workflows) | 45.4 | 39.1 | 32.1 | 41.6 | 41.2 |
| GDP.pdf (professional work) | 33.2 | 30.8 | 27.6 | 34.2 | 30.6 |
| JobBench (professional tool use) | 75.3 | 70.5 | 73.1 | 66.1 | 75.4 |
| OSWorld V2.1 (computer use, partial) | 78.4 | 72.6 | 80.7 | 75.8 | 81.8 |
| MemoryBench (internal) | 85.5 | 85.6 | 79.0 | 81.4 | 81.5 |
| Terminal-Bench 4.0-AA | 57.1 | 52.0 | 52.0 | 59.1 | 59.6 |
| DeepSWE 1.1 (long coding) | 79.0 | 78.8 | 67.4 | 74.1 | 74.2 |
| SWE-Marathon (very long projects) | 57.5 (xhigh) | 53.1 | 45.6 | 42.5 | 46.3 |
| ProgramBench (from scratch) | 59.0 | 50.0 | 55.5 | 52.5 | 70.5 |
| Artificial Analysis Index (headline row) | 56 | 52 | 53 | 53 | 58 |
Read the table as a pattern rather than a scoreboard. Wonder Full leads six rows in Meta’s own chart, including Harvey LAB-AA (13.1 against 4.2 for Opus 5.5), AutomationBench-AA (45.4), DeepSWE 1.1 (79.0 against 74.2) and SWE-Marathon. Muse Wonder leads MemoryBench. Opus 5.5 leads six rows, including ProgramBench (70.5 against 59.0), Terminal-Bench, HealthBench Pro and OSWorld, and GPT-6 Astra leads GDP.pdf. In other words, Meta is strongest on long-horizon agentic work and weakest where Opus 5.5 is traditionally strong: building from scratch and operating a computer.
The independent Artificial Analysis Intelligence Index (v4.3.2, as quoted by Fello AI) tells a more conservative story: Opus 5.5 on 58, Claude Sonnet 5.5 on 56, Wonder Full on 56, Fable 5.1 and GPT-6 Astra on 53, and Muse Wonder on 52. That puts Wonder Full level with Sonnet 5.5 and above Astra, but below Opus 5.5. It also means the cheaper Muse Wonder you can actually call through the API sits below both Fable 5.1 and Astra on that index. See our Opus 5.5 review and Sonnet 5.5 review for the benchmarks on the Anthropic side.
Why the Comparison Is Shakier Than It Looks
Fello AI’s analysis lists several caveats that we think are fair, and they are visible in Meta’s own footnotes. First, the chart is self-reported: where no third-party score exists, Meta uses the highest of its internal, self-reported or leaderboard scores. Second, two rows (Personal Superintelligence Index and MemoryBench) are Meta’s internal benchmarks, and they are exactly the rows that favour Meta’s product thesis. Third, Meta calls its rival runs “best-effort” and says prompts and tools “may not be optimally tuned for proprietary models”. Fourth, the SWE-Marathon headline uses Wonder Full at xhigh effort while the rest of the table uses max, and Meta says the row is “not a controlled common-harness comparison”.
None of this makes the numbers wrong. It means they are the numbers a company chooses to publish about itself, which is true of every vendor chart, including those from Anthropic and OpenAI. The practical response is to run your own tasks. WorldofAI’s video does exactly that with its WoAI Bench tool, and the title’s scepticism (“I don’t think so”) is a reminder that a benchmark win and a good day-to-day experience are different things.
Pricing and Context Window
Muse Wonder lists at $4 per million input tokens, $0.20 for cached input and $20 per million output tokens, with a 1 million token context window. Inputs can be text, images, video and audio, and output is text only. At current exchange rates that is roughly £3 input and £15 output per million tokens. Here is how it compares with the rivals Fello AI lists.
| Model | Input | Cached input | Output |
|---|---|---|---|
| Muse Wonder | $4 | $0.20 | $20 |
| Claude Opus 5.5 | $4 | $0.20 | $20 |
| Claude Sonnet 5.5 | $2 | $0.10 | $10 |
| Claude Fable 5.1 | $10 | $0.25 | $50 |
| GPT-6 Astra | $10 | $1.00 | $50 |
| Muse Spark 1.3 | $1.25 | $0.15 | $4.25 |
Two observations. Muse Wonder costs exactly the same as Claude Opus 5.5, and beats it on only five of 14 chart rows, so the price case rests on specific strengths rather than a general discount. Fello AI also notes that Alexandr Wang had said pricing would be “meaningfully below” OpenAI and Anthropic, which is true against Fable 5.1 and Astra but not against Opus 5.5. Against Fable 5.1 and Astra, at $10 and $50, Wonder is far cheaper for a similar Artificial Analysis score. For cost-sensitive teams, our comparison of GPT-6 Sol and Claude Opus 5.5 shows how quickly the price tiers have shifted.
Safety and Evaluation
Meta says the models were trained, evaluated and released under its Meta Superintelligence Scaling Framework, and that they were trained to refuse requests to help with actually harmful acts and to avoid sharing private information without permission. It also positions them as useful for defenders, saying developers and security teams can use them to find flaws in their own code.
The more notable disclosures come from Fello AI’s reading of the model card: Meta says it cannot rule out Wonder Full reaching its high-risk threshold for chemical and biological misuse without mitigations, and in a cyber exploitation evaluation called ExploitGym only 21 of 92 flags used the intended vulnerability. Meta says a full report with additional safety evaluations will be available soon. Until it is, we have no independent view of how the model behaves under adversarial testing, and we will update this guide when the report is published. For how other labs have framed similar thresholds, see our coverage of OpenAI Astra’s critical cyber threshold.
How Muse Wonder Compares
There is also the wider rumour mill. Creators are already speculating about Anthropic’s next release, and we have separately checked those claims in our Opus 6 leak article and our guide to the next Claude model. If a new Claude lands soon, the comparison above will move.
Who Should Try It
- Agent builders running long tasks: test Muse Wonder on your own multi-hour workflows. Meta’s strongest rows are DeepSWE and SWE-Marathon.
- Teams paying Fable 5.1 or Astra prices: a trial could cut cost sharply if your tasks match Wonder’s strengths.
- Anyone building on memory: Active Memory is the differentiator, but verify it on real, messy user data.
- Not yet: regulated or safety-critical work, until the full safety report and independent evaluations arrive.
The Bottom Line
Muse Wonder is a serious release that puts Meta back in the frontier conversation on price, context length and agentic work. It is not a clean win over Opus 5.5, and its most flattering numbers are internal or self-reported. Test it where it is strongest, compare it on your own tasks, and keep an eye out for Meta’s promised safety report and for independent leaderboards before making it a default.
Sources
- Meta: Introducing Muse Wonder and Muse Wonder Full (12/10/2026): models, access, Active Memory, Active Focus, safety framework.
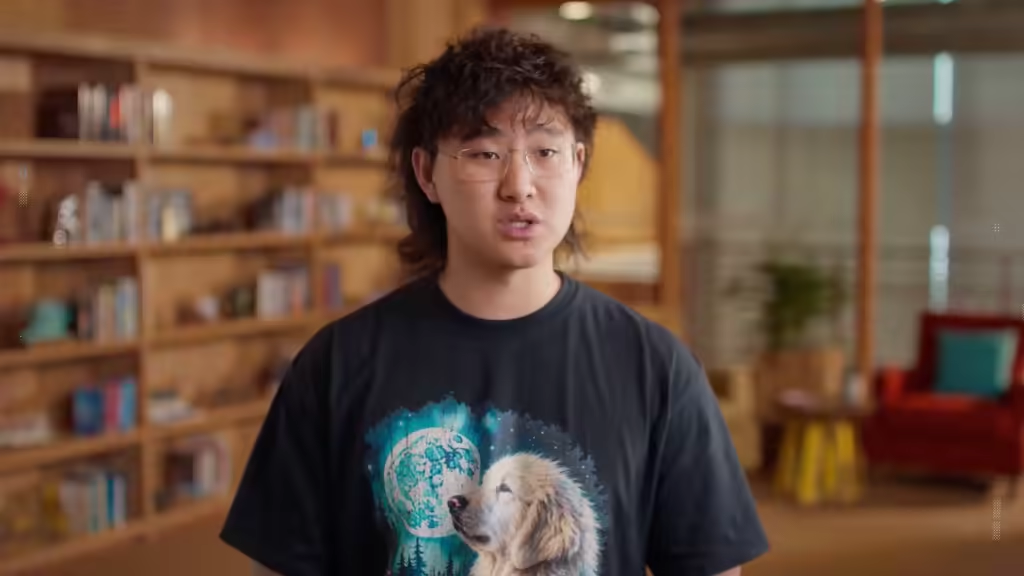
- TechCrunch: Meta releases its first frontier model, Muse Wonder: positioning, pricing, MemoryBench, Prometheus data centre. Hero image: still from Meta’s launch video as published by TechCrunch (credit: Meta).
- Fello AI: Meta Muse Wonder: Benchmarks, Price and the Catch: transcription of Meta’s benchmark chart, Artificial Analysis scores, pricing comparison, caveats. Secondary source.
- CNBC: Meta debuts Muse Wonder AI model: Muse app subscription tiers.
- Quartz: Meta launches Muse Wonder: codename and positioning.
- OpenRouter: Muse Wonder: 1M-token context listing.
- Matthew Berman on YouTube (13/10/2026) and WorldofAI on YouTube (12/10/2026).
Last updated: 13/10/2026. Benchmark figures are Meta’s self-reported numbers as transcribed by Fello AI; we could not open Meta’s model card directly. Meta has promised a fuller safety report.
Get the free guide: Claude vs ChatGPT, Gemini & Grok
A 20-page playbook covering everything you need to choose and use the big four AI models in 2026, full cost and feature comparisons, what each is best (and worst) at, and how-tos for images, vectors, building a website, Claude Code and more.